

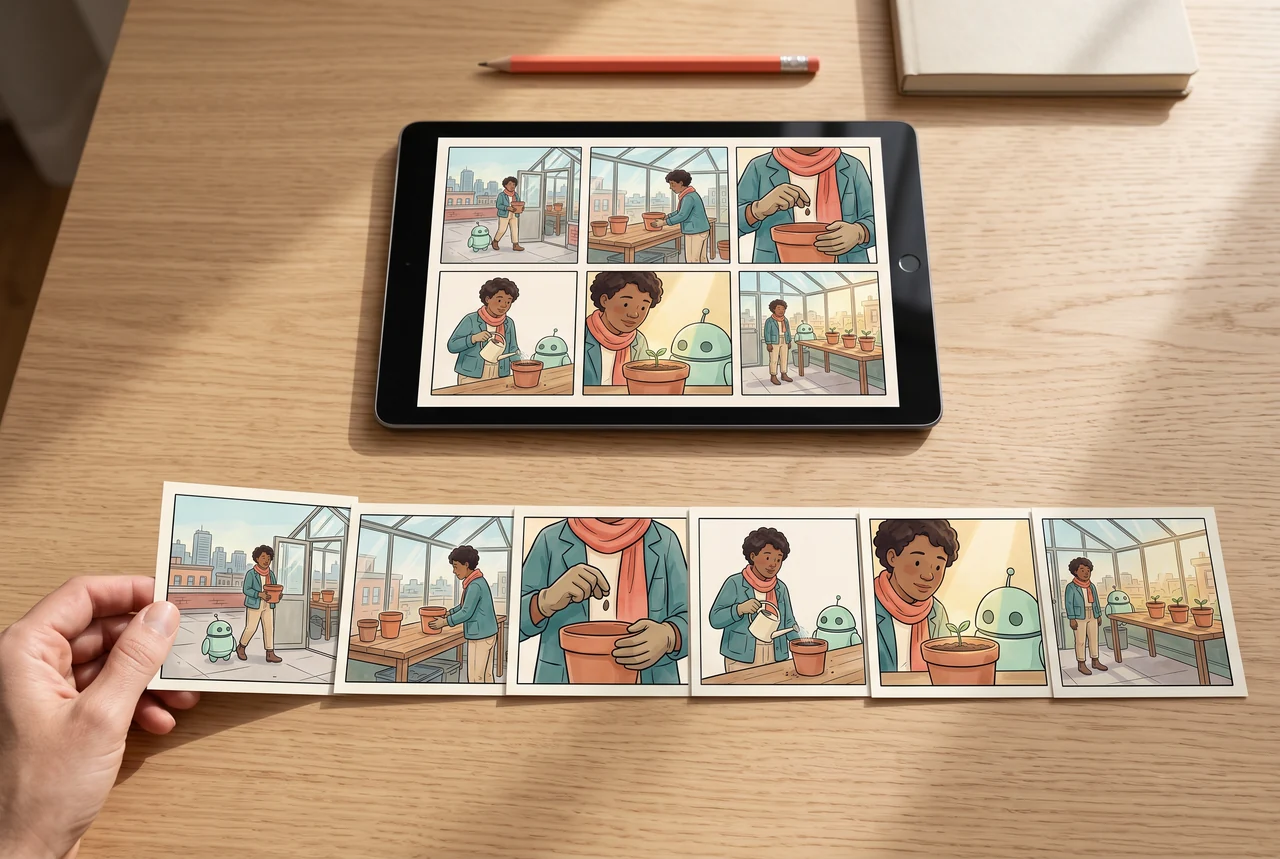
AI comic understanding is the process of turning a comic page or sequence into structured information about its visual and narrative parts: panels, reading order, characters, actions, dialogue, objects, settings and relationships between scenes.
A model that can describe one image may still misunderstand a comic. It might identify a person and a speech bubble but miss who is speaking, which panel comes first, what changed between panels or why a prop matters. Comic understanding is therefore a sequence problem, not only an image-captioning problem.
The short definition
AI comic understanding is the structured interpretation of comic pages and panels so that a system can reason about visual content and narrative relationships across a sequence.
A useful representation needs both local evidence—what appears inside a panel—and cross-panel context—how that panel relates to the story before and after it.
A comic page contains several connected structures
1. Page and panel structure
The system must identify panel boundaries, gutters, overlapping frames, inset panels and page-level layout. It should preserve the original artwork and reading order rather than assuming every page is a simple grid.
2. Reading order
The order in which panels are read is part of the story. Layouts can vary by language, genre and artistic convention. A robust system should infer a likely order, expose uncertainty and allow a creator to correct it.
3. Characters and roles
The system needs to distinguish recurring characters, background figures and newly introduced subjects. It should also connect a character to a role in the current panel: speaker, listener, actor, observer or off-panel participant.
4. Dialogue and text
OCR can extract visible lettering, but understanding dialogue also requires associating a speech bubble with the right speaker and panel. Captions, sound effects, labels and signs should not all be treated as spoken dialogue.
5. Actions, objects and relationships
A panel may show one character handing a prop to another, looking toward a door or reacting to an event outside the frame. The relation between entities often matters more than the object labels themselves.
6. Narrative state
A sequence can establish facts that later panels depend on: who has an object, where the scene takes place, which character is injured or what has already happened. These facts should be tracked with their source and time scope.
From pixels to a structured story representation
A practical system can combine multiple stages. This is an architecture pattern, not a claim that one vision model performs every step perfectly.
- Page ingestion: preserve the original image, dimensions, source and page identity.
- Panel segmentation: detect panel regions, gutters and overlapping layouts.
- Reading-order inference: propose the sequence and flag ambiguous layouts.
- Text extraction: read dialogue, captions and sound effects while retaining their coordinates.
- Entity resolution: connect recurring characters, props and locations to known references.
- Visual relation extraction: describe actions, spatial relationships, gaze, pose and interaction.
- Narrative linking: connect the current panel to earlier and later story events.
- Human correction: let the creator approve panel order, character identity and facts before they become canonical memory.
The output should retain references back to the source page and region. A generated summary without provenance is difficult to audit when a later page contradicts it.
A lightweight scene graph for comic reasoning
One useful representation is a graph:
- Nodes: panels, characters, objects, locations, dialogue blocks and story events.
- Edges: appears-in, speaks-in, holds, looks-at, interacts-with, precedes, causes or contradicts.
- Attributes: page number, panel bounds, viewpoint, confidence, source region and time scope.
For example, a panel might record that Character A holds the brass key in the observatory, while the next panel records that the key is on the floor. The relationship is not just an object-detection result; it is a state change that may matter later.
The graph should distinguish observed facts from model inferences. “A key is visible in the character's hand” is an observation. “The character has stolen the key” is an interpretation that may need confirmation.
Why this matters for generation and editing
Structured understanding can support several downstream tasks:
- Character continuity: retrieve the right identity and appearance references for the current scene.
- Storyboard planning: turn story beats into panel-level actions, cast and camera instructions.
- Natural-language editing: understand which character, object or region the user means.
- Animation preparation: preserve panel order, shot intent and important dialogue space.
- Publishing: check page order, text placement and output specifications.
This connects to LlamaGen's existing comic storyboard workflow, single-panel planning and AI comic creation workspace.
Research shows why sequence-level evaluation matters
DiffSensei studies customized manga generation with multiple characters, panel-specific actions and layout control. It illustrates why a system needs to connect character identity with the specific requirements of a panel rather than treating every image as an unrelated prompt.
ViStoryBench, accepted at CVPR 2026, evaluates story visualization across narrative structures, character references and visual styles. Its metric suite separates dimensions such as character consistency, style similarity, prompt alignment, aesthetic quality and diversity. That separation is useful because one overall image score can hide a failure in story or identity.
ViStoryBench project and benchmark.
These papers provide research context. They are not benchmarks of LlamaGen or evidence that the same architectures are deployed in CyaniModel.
How to evaluate comic understanding
A review protocol should test each layer independently.
| Capability | Example check |
|---|---|
| Panel segmentation | Are all panel regions found without merging adjacent scenes? |
| Reading order | Does the inferred order match the intended sequence? |
| OCR and association | Is dialogue extracted and linked to the correct bubble and speaker? |
| Character resolution | Are recurring characters distinguished from similar-looking subjects? |
| Action and relation | Does the system correctly identify who did what to whom? |
| State tracking | Are important objects, outfits and scene changes represented at the right point? |
| Narrative coherence | Does the summary preserve cause, consequence and panel-to-panel progression? |
| Provenance | Can every important claim be traced to a source panel or user confirmation? |
Automated evaluation should be paired with creator review. Stylized characters, unusual layouts, manga reading directions and deliberately ambiguous storytelling can challenge generic vision metrics.
What CyaniModel and DeepStory contribute
CyaniModel focuses on the visual-creation side: controlled generation, reference-led workflows and panel-level review. DeepStory is the complementary context concept: a persistent, source-backed record of characters, story facts, relationships and changes that can be retrieved when a later task needs them.
The distinction is important. Visual understanding extracts evidence from a page. Story memory organizes approved facts over time. A generation agent then uses the relevant context to create the next panel.
This is the intended architecture direction, not a statement that every scene graph, OCR association or persistent memory feature is already available in the product.